"Database Is Locked": The Night Our Support Bot Gave Up 7 Times
A SQLite 'database is locked' storm took down our claims bot for an evening: 300+ errors, 7 chats abandoned. Ordinary cause, two-line fix.
Most “AI bot” outages are not AI outages. This one was a SQLite file and a thread pool having a disagreement, and I’m writing it up because every tutorial on “running concurrent bots” skips straight past it, whistling.
What the bot does
Every closed support chat gets summarised by Claude and written as a row to our claims sheet. To make that fast, three summaries run in parallel. The bot keeps its local state in a SQLite file: which chats are done, which photos it has already shown, how many times it has retried something.
What happened
On the evening of 2 October the log filled up with this, over and over, like a toddler who’s learned one word:
[CRM] photo index failed — database is locked
sqlite3.OperationalError: database is locked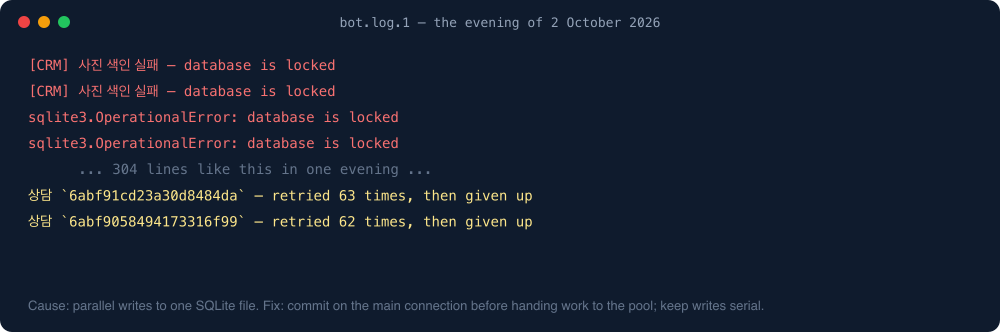
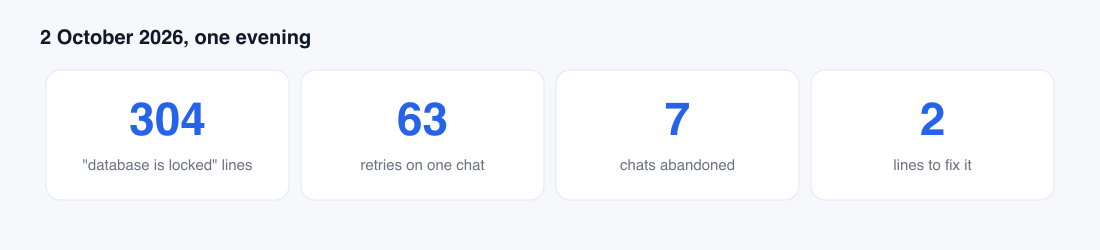
304 lines in a few hours. Two chats were retried more than 60 times each before the bot finally gave up on them. Seven chats in total were abandoned that night. And because an alert fired for every retry, my DM looked like a slot machine that only pays out in red.
Why
SQLite allows exactly one writer at a time. That’s fine when your writes are short and polite and take turns. Mine weren’t, in two ways:
- The main thread opened a transaction and didn’t commit it before handing work to the thread pool. The workers then tried to write to a file the main connection was still sitting on.
- The workers’ writes were parallel. Three summaries finished at once, all three tried to update state, each blocked the others, the retry loop kicked in, and the retries made the contention worse. A traffic jam where every car honks and the honking causes more cars.
Nothing about the model, the prompt or Slack changed that day. The load was slightly higher than usual. That was all it took.
The fix
Two changes, both so boring I almost didn’t write this post:
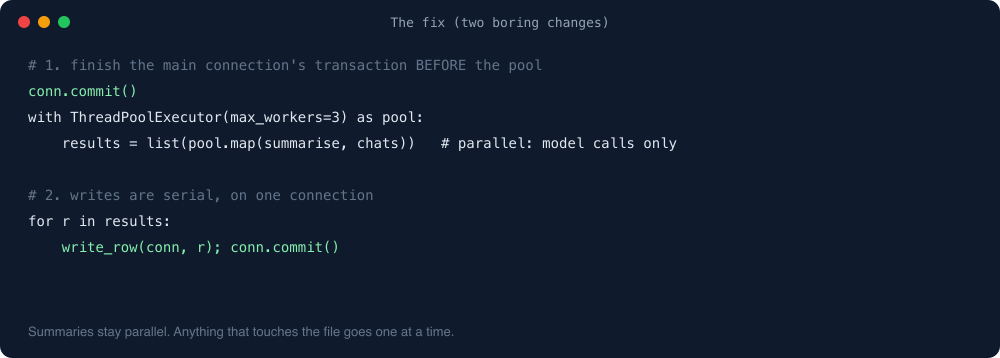
# before handing work to the pool, finish the main connection's transaction
conn.commit()
with ThreadPoolExecutor(max_workers=3) as pool:
    results = list(pool.map(summarise, chats))   # parallel: model calls only

# writes are serial, on the main connection
for r in results:
    write_row(conn, r)
    conn.commit()
Summaries stay parallel; they’re model calls and never touch the file. Everything that writes to SQLite or to the sheet happens on one connection, one at a time, like adults. The outage hasn’t recurred.
The second-order fix
The alert storm was its own problem. Each retry posted an alert, so one root cause produced a hundred notifications and I nearly threw my phone into the sea. Now:
- Retries don’t alert. Only the final give-up does, once, with the retry count attached.
- Identical errors inside 30 minutes collapse to one line.
- All bot errors go to one person’s DM, not a channel.
What I’d check first next time
- Is there an uncommitted transaction on the main connection?
- Are any writes running in parallel?
- Is the retry loop making the lock contention worse?
In that order. It was all three. It’s usually all three.
One line from me
None of this is hard. It’s the tedious, soul-sucking grunt work nobody wants to do. Hand every bit of it to the bot.